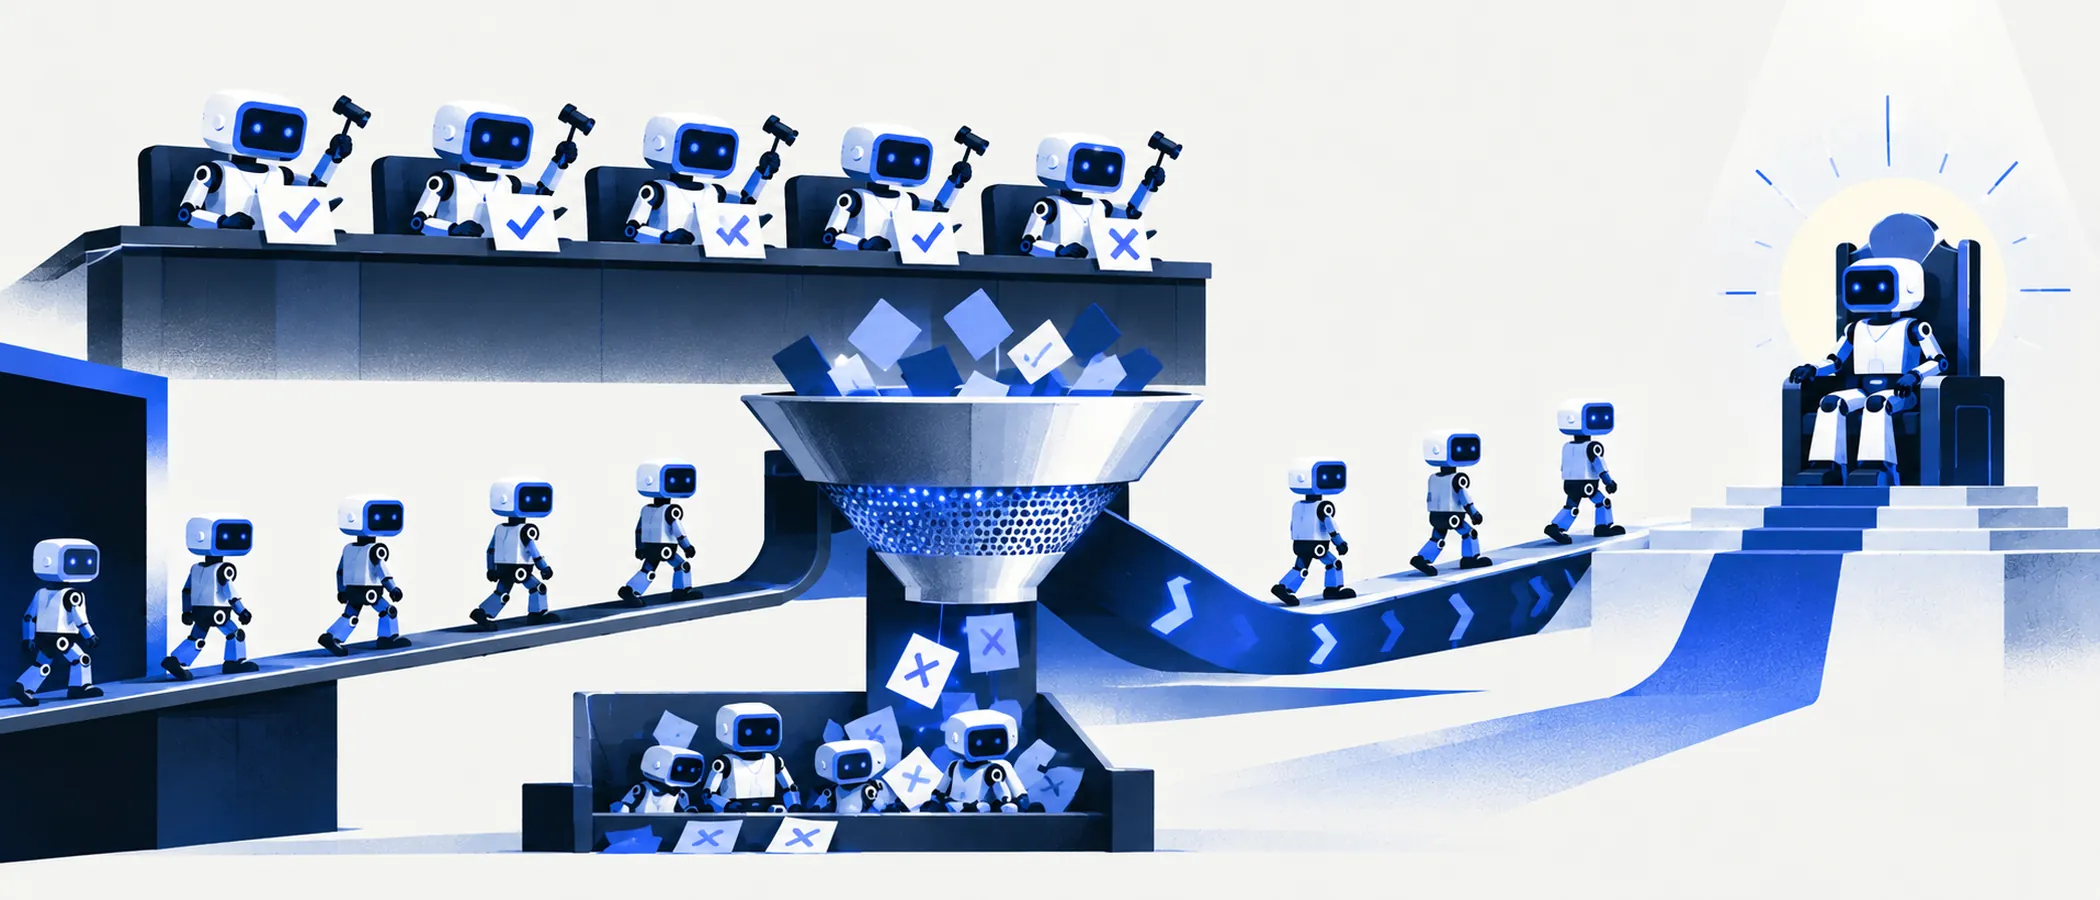
Evaluating a fine-tuned coaching model usually takes domain experts as reviewers. That is slow and expensive. An LLM as a judge is cheaper, but without reference values its verdicts can't simply be trusted. According to a preprint on arXiv, a staged pipeline is meant to help weed out candidates before expert review.
How the pipeline works
Judge models and the student models being evaluated go through several stages, each with explicit decision rules. The checks cover the judges' own outputs, their similarity to hosted judges, possible biases, and the robustness of the decision. The final stage would be anchoring to expert judgment. The paper proposes it but does not carry it out.
The example is an AI coach for dental hygiene. The training and reference data are synthetic and not clinically validated. The case study therefore shows how the pipeline works. It says nothing about the clinical quality of the models.
What the case study shows
The study compared two small language models, Granite-4.1-8B and Qwen3-8B, each trained with three data sizes. Five judges scored them on seven metrics, three of the judges running locally and two hosted. Two local judges, Qwen3.8-27B and Gemma-4-31B-it, were indistinguishable by rank correlation from the agreement between the two hosted judges on six of seven metrics. Overall, Qwen3.8-27B was the most similar to the hosted judges. No judge met the criterion for favoring its own model family or its own data source.
The pipeline did not separate the two student models on any metric. Granite-4.1-8B came out ahead in 29 of 35 combinations of judge and metric. The authors treat this only as a tendency, because it partly depends on truncated outputs from Qwen3-8B.
The pipeline also exposed problems that were lost in the raw scores. These include the truncated outputs and hallucination flags from one hosted judge that no other judge confirmed.
- Jev: fast, cheap evaluation of clinical AI answers
- OR-License: How Good Are LLM Agents at Operations Research?
- PAWM: World Model Warns LLM Agents of Pitfalls
Assessment
No dental hygiene specialist rated the answers, so the results are preliminary. Even so, the approach can be useful for teams with similar tasks. Judge models can be checked for anomalies beforehand, and scarce expert time can be directed to the remaining candidates.


